Latest [Nov 18, 2026] Real Microsoft DP-750 Exam Dumps Questions [Q14-Q37]

Rate this post

Latest [Nov 18, 2026] Real Microsoft DP-750 Exam Dumps Questions

DP-750 Dumps To Pass Microsoft Certified: Fabric Data Engineer Associate Exam in One Day (Updated 93 Questions)

Microsoft DP-750 Exam Syllabus Topics:

Section Weight Objectives
Configure and manage Azure Databricks environments 15-20% – Security and authentication setup

  • 1. Service principals and managed identities
    • 2. Azure Key Vault integration
      • 3. Access control for compute resources

        – Workspace and compute configuration

        • 1. Autoscaling, termination, and performance tuning
          • 2. Runtime, Spark, and Photon configuration
            • 3. Cluster types and configuration (job, all-purpose, serverless)
              Deploy and manage data pipelines and workloads 30-35% – Lakehouse architecture operations

              • 1. Delta Lake optimization and clustering strategies
                • 2. Delta Live Tables pipelines

                  – Pipeline design and orchestration

                  • 1. Notebook-based vs declarative pipelines
                    • 2. Databricks Jobs and Workflows

                      – Operational reliability

                      • 1. Monitoring and logging (Azure Monitor integration)
                        • 2. Error handling and retries
                          Prepare and process data 30-35% – Data quality and validation

                          • 1. Handling nulls, duplicates, and missing data
                            • 2. Pipeline expectations and data quality constraints
                              • 3. Schema enforcement and validation rules

                                – Data ingestion

                                • 1. Batch ingestion using COPY INTO and CTAS
                                  • 2. Streaming ingestion using Spark Structured Streaming
                                    • 3. Auto Loader and CDC ingestion patterns

                                      – Data transformation and modeling

                                      • 1. SQL and PySpark transformations
                                        • 2. Joins, aggregations, and normalization/denormalization
                                          • 3. Delta Lake table design and SCD patterns
                                            Secure and govern data using Unity Catalog 15-20% – Data governance fundamentals

                                            • 1. Data lineage and auditing
                                              • 2. Catalog, schema, and table management

                                                – Access control and policies

                                                • 1. Attribute-based access control (ABAC)
                                                  • 2. Row-level and column-level security
                                                    • 3. Tags and policy enforcement


                                                      NO.14 You have an Azure Databricks workspace that contains a Git folder and uses Azure Repos as the Git provider.
                                                      From the main branch, you create a branch named Branch1. You commit changes to Branch1.
                                                      You need to incorporate the changes from Branch1 into main. The solution must preserve the commit history in the repository.
                                                      Which command should you run?


                                                      NO.15 You use Databricks Asset Bundles to manage two jobs and an app.
                                                      You need to deploy the bundle to development and production environments. The solution must meet the following requirements:
                                                      – Deploy the app to both environments.
                                                      – Deploy only one job to development.
                                                      – Minimize administrative effort.
                                                      What should you use?


                                                      NO.16 You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
                                                      NOTE: Each correct selection is worth one point.

                                                      NO.17 You have an Azure Databricks workspace that is enabled for Unity Catalog.
                                                      You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
                                                      * Ensure that authentication does NOT require storing credentials in Databricks
                                                      * Ensure that users can access the files, but NOT modify the files.
                                                      * Follow the principle of least privilege
                                                      Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
                                                      NOTE: Each correct selection is worth one point.

                                                      NO.18 What improves join performance for small lookup tables?


                                                      NO.19 You need to develop the task logic for a new job in Lakeflow Jobs that processes telemetry data.
                                                      Each task must contain only the appropriate logic for its step in the pipeline. The solution must support the planned changes and meet the data ingestion and processing requirements.
                                                      What should you do?


                                                      NO.20 You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two managed Delta tables named sales.schema1.table1 and sales.schema1.table2.
                                                      sales.schema1.table1 contains sales data from the current year.
                                                      sales.schema1.table2 contains historical data.
                                                      You need to load all the rows from sales.schema1.table1 into sales.schema1.table2. The solution must preserve any existing data in sales.schema1.table2 and minimize processing effort.
                                                      Which command should you run?


                                                      NO.21 Which layer contains cleaned and conformed data in Databricks Lakehouse architecture?


                                                      NO.22 You have an Azure Databricks workspace that is enabled for Unity Catalog.
                                                      You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
                                                      You need to modify rule1 to meet the following requirements:
                                                      – Ensure that amount is always greater than 0.
                                                      – Prevent an update to Table1 from being committed when data that
                                                      violates rule1 is detected.
                                                      Which statement should you execute?


                                                      NO.23 You have an Azure Databricks workspace that contains a Delta table named Table1.
                                                      Table1 has accumulated obsolete files.
                                                      You need to reduce storage costs. The solution must preserve 30 days of time travel history.
                                                      Which two actions should you perform? Each correct answer presents part of the solution.
                                                      NOTE: Each correct selection is worth one point.


                                                      NO.24 You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
                                                      You have a connection to a Microsoft SQL Server database named DB1.
                                                      You need to expose the schemas and tables of DB1 to meet the following requirements:
                                                      * The schemas and tables can be queried in Databricks.
                                                      * The schemas and tables appear alongside other Unity Catalog objects.
                                                      * The data is NOT copied into Databricks-managed storage.
                                                      Solution: You create a Lakeflow Connect pipeline and connect it to DB1. Does this meet the goal?


                                                      NO.25 You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
                                                      You need to configure Cluster1 to meet the following requirements:
                                                      – The cluster must scale up automatically when workloads increase.
                                                      – The cluster must scale down automatically when workloads decrease.
                                                      The solution must minimize costs.
                                                      Which two actions should you perform? Each correct answer presents part of the solution.
                                                      NOTE: Each correct selection is worth one point.


                                                      NO.26 You need to configure the telemetry pipeline to support the planned changes for pipeline orchestration and address the resiliency issues.
                                                      What should you do?


                                                      NO.27 You have an Azure Databricks workspace that contains a Delta table named Customer.
                                                      A job named Job1 performs frequent upserts into Customer.
                                                      You discover that Job1 has created many small Parquet files in Customer, and the small files are degrading query performance.
                                                      You need to improve query performance for the current data already stored in Customer. The solution must not affect the travel for the Customer table.
                                                      What should you do?


                                                      NO.28 A Delta table receives new fields in incoming JSON data. You want to automatically adapt without breaking pipelines. What should you enable?


                                                      NO.29 You need to ingest real-time IoT data into Delta Lake with exactly-once guarantees. Which approach should you use?


                                                      NO.30 Case Study 1 – Contoso, Inc.
                                                      Overview
                                                      Company Information
                                                      Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
                                                      Existing Environment
                                                      Azure Environment
                                                      Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
                                                      Workspace1 contains all-purpose clusters for both development and production workloads.
                                                      The company’s Azure environment contains:
                                                      – In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
                                                      – A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
                                                      – An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
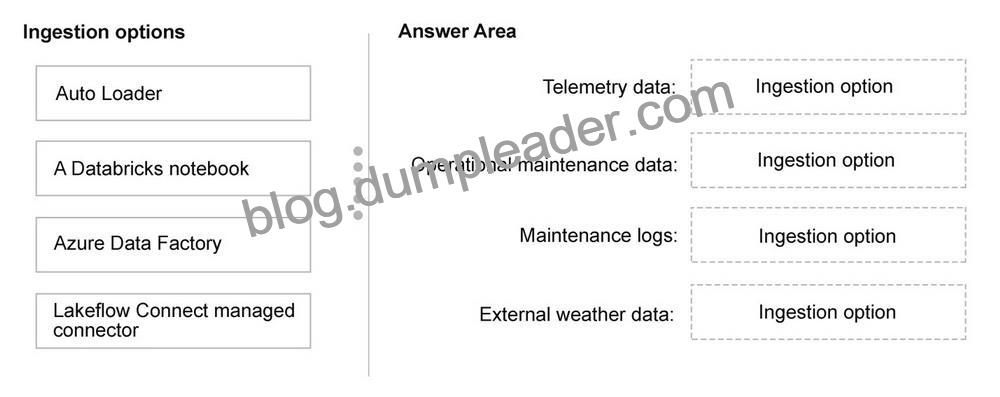
                                                      – Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
                                                      – Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
                                                      – Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
                                                      – External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
                                                      – ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
                                                      Problem Statements
                                                      The company’s existing analytics environment has several issues:
                                                      Ingestion
                                                      – Telemetry pipelines fall behind during peak loads.
                                                      – Telemetry ingestion fails when schema drift occurs.
                                                      – Streaming pipelines reprocess events after a pipeline restarts.
                                                      Compute
                                                      Production and development workloads run on the same all-purpose clusters.
                                                      Production and development workloads do NOT support autoscaling or workload isolation.
                                                      Governance
                                                      – The ERP data is duplicated across systems and development teams.
                                                      – Naming conventions are inconsistent across development teams, regions, and products.
                                                      – Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
                                                      – Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
                                                      Historical values are NOT required.
                                                      Pipeline operations
                                                      – Pipelines lack resiliency, alerting, and centralized scheduling.
                                                      Requirements
                                                      Planned Changes
                                                      Contoso plans to implement the following changes:
                                                      – Implement scalable data pipeline orchestration.
                                                      – Create a managed analytics catalog in Unity Catalog.
                                                      – Implement a consistent approach to creating curated datasets.
                                                      – Establish a centralized governance model across ingestion, cleansed, and curated layers.
                                                      – Grant data engineers access to the ERP tables by using minimal development effort.
                                                      – Adopt a compute strategy that isolates production workloads and supports autoscaling.
                                                      – Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
                                                      Technical Requirements
                                                      Contoso identifies the following environment and compute requirements:
                                                      – Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
                                                      – Provide fast and consistent performance for business intelligence (BI) workloads.
                                                      – Prevent development activity from affecting production pipelines.
                                                      – Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
                                                      Contoso identifies the following data ingestion and processing requirements:
                                                      – Auto-scale ingestion pipelines to handle bursty workloads.
                                                      – Handle schema drift for the maintenance and telemetry data.
                                                      – Ingest file-based telemetry data by using minimal operational effort.
                                                      – Store all the ingested data in a format that supports incremental processing.
                                                      – Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
                                                      – Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
                                                      – Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
                                                      – Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
                                                      Contoso identifies the following data modeling and optimization requirements:
                                                      – Build curated tables that standardize business logic.
                                                      – Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
                                                      Contoso identifies the following pipeline deployment and operation requirements:
                                                      – Orchestrate multi-step ingestion and transformation workflows.
                                                      – Define a clear execution order and dependencies.
                                                      – Automatically retry failed steps and notify operators.
                                                      – Schedule ingestion and transformation workloads consistently.
                                                      Governance Requirements
                                                      Contoso identifies the following governance requirements:
                                                      – Centralize the metadata catalog.
                                                      – Provide isolated development areas that follow standard naming conventions.
                                                      – Establish a consistent structure for organizing raw, cleansed, and curated data.
                                                      – Provide a read-only mechanism to reference the ERP data through a foreign catalog.
                                                      Business Requirements
                                                      Contoso identifies the following business requirements:
                                                      – Improve ingestion reliability and reduce operational effort.
                                                      – Standardize data definitions across development teams.
                                                      Drag and Drop Question
                                                      Which ingestion option should you recommend for each data source? To answer, drag the appropriate options to the correct data sources. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
                                                      NOTE: Each correct selection is worth one point.
                                                      NO.31 What improves join performance for small lookup tables?


                                                      NO.32 Case Study 1 – Contoso, Inc.
                                                      Overview
                                                      Company Information
                                                      Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
                                                      Existing Environment
                                                      Azure Environment
                                                      Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
                                                      Workspace1 contains all-purpose clusters for both development and production workloads.
                                                      The company’s Azure environment contains:
                                                      – In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
                                                      – A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
                                                      – An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
                                                      – Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
                                                      – Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
                                                      – Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
                                                      – External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
                                                      – ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
                                                      Problem Statements
                                                      The company’s existing analytics environment has several issues:
                                                      Ingestion
                                                      – Telemetry pipelines fall behind during peak loads.
                                                      – Telemetry ingestion fails when schema drift occurs.
                                                      – Streaming pipelines reprocess events after a pipeline restarts.
                                                      Compute
                                                      Production and development workloads run on the same all-purpose clusters.
                                                      Production and development workloads do NOT support autoscaling or workload isolation.
                                                      Governance
                                                      – The ERP data is duplicated across systems and development teams.
                                                      – Naming conventions are inconsistent across development teams, regions, and products.
                                                      – Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
                                                      – Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
                                                      Historical values are NOT required.
                                                      Pipeline operations
                                                      – Pipelines lack resiliency, alerting, and centralized scheduling.
                                                      Requirements
                                                      Planned Changes
                                                      Contoso plans to implement the following changes:
                                                      – Implement scalable data pipeline orchestration.
                                                      – Create a managed analytics catalog in Unity Catalog.
                                                      – Implement a consistent approach to creating curated datasets.
                                                      – Establish a centralized governance model across ingestion, cleansed, and curated layers.
                                                      – Grant data engineers access to the ERP tables by using minimal development effort.
                                                      – Adopt a compute strategy that isolates production workloads and supports autoscaling.
                                                      – Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
                                                      Technical Requirements
                                                      Contoso identifies the following environment and compute requirements:
                                                      – Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
                                                      – Provide fast and consistent performance for business intelligence (BI) workloads.
                                                      – Prevent development activity from affecting production pipelines.
                                                      – Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
                                                      Contoso identifies the following data ingestion and processing requirements:
                                                      – Auto-scale ingestion pipelines to handle bursty workloads.
                                                      – Handle schema drift for the maintenance and telemetry data.
                                                      – Ingest file-based telemetry data by using minimal operational effort.
                                                      – Store all the ingested data in a format that supports incremental processing.
                                                      – Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
                                                      – Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
                                                      – Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
                                                      – Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
                                                      Contoso identifies the following data modeling and optimization requirements:
                                                      – Build curated tables that standardize business logic.
                                                      – Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
                                                      Contoso identifies the following pipeline deployment and operation requirements:
                                                      – Orchestrate multi-step ingestion and transformation workflows.
                                                      – Define a clear execution order and dependencies.
                                                      – Automatically retry failed steps and notify operators.
                                                      – Schedule ingestion and transformation workloads consistently.
                                                      Governance Requirements
                                                      Contoso identifies the following governance requirements:
                                                      – Centralize the metadata catalog.
                                                      – Provide isolated development areas that follow standard naming conventions.
                                                      – Establish a consistent structure for organizing raw, cleansed, and curated data.
                                                      – Provide a read-only mechanism to reference the ERP data through a foreign catalog.
                                                      Business Requirements
                                                      Contoso identifies the following business requirements:
                                                      – Improve ingestion reliability and reduce operational effort.
                                                      – Standardize data definitions across development teams.
                                                      Hotspot Question
                                                      You need to complete the PySpark code for the Spark Structured Streaming pipelines. The solution must meet the data ingestion and processing requirements.
                                                      How should you complete the code segment? To answer, select the appropriate options in the answer area.
                                                      NOTE: Each correct selection is worth one point.
                                                      NO.33 You have an Azure Databricks workspace named Workspace1 that contains a takehouse and is enabled for Unity Catalog.
                                                      You have a connection to a Microsoft SQL Server database named DB1.
                                                      You need to expose the schemas and tables of DB1 to meet the following requirements:
                                                      * The schemas and tables can be queried in Databricks.
                                                      * The schemas and tables appear alongside other Unity Catalog objects.
                                                      * The data is NOT copied into Databricks-managed storage.
                                                      Solution: You create a new native catalog in Unity Catalog. Does this meet the goal?


                                                      NO.34 You have an Azure Databricks workspace that is attached to a Unity Catalog metastore named metastore1, metastore1 contains a catalog named catalog1.
                                                      You need to create a new schema named schema2 that meets the following requirements:
                                                      – Is contained in catalog1
                                                      – Uses abfss://[email protected]/data as
                                                      the managed location
                                                      Which SQL statement should you execute?


                                                      NO.35 You have an Azure Databricks workspace that contains a Git folder and uses Azure Repos as the Git provider.
                                                      From the main branch, you create a branch named Branch1. You commit changes to Branch1.
                                                      You need to incorporate the changes from Branch1 into main The solution must preserve the commit history in the repository. Which command should you run?


                                                      NO.36 You have an Azure Databricks workspace named Workspace1 that uses a Git repository. The repository contains a Databricks notebook named Notebook1.
                                                      From the main branch, you create a feature branch named Branch1 and commit changes to Notebook1. Another user commits changes to Notebook1 in main.
                                                      When you attempt to merge Branch1 into main, the merge fails due to conflicts.
                                                      You need to merge Branch1 into the main branch. The solution must ensure that Notebook1 includes all the changes from both the branches.
                                                      What should you do?


                                                      NO.37 You have an Azure Databricks workspace that contains the objects shown in the following table.
                                                      Name | Type
                                                      Catalog1 | Catalog
                                                      Schema1 | Schema
                                                      Sales1 | Table
                                                      Notebook1 | Notebook
                                                      Space1 | AI/BI Genie space
                                                      Users often use the following words to refer to a sale: transaction, event, order, and invoice.
                                                      You need to create a knowledge store. The solution must ensure that when the users use any of the words in Space1, Genie queries the Sales1 table. Any other Genie spaces must remain unaffected.
                                                      To which object should you add the instructions?


                                                      DP-750 Exam Brain Dumps – Study Notes and Theory: https://www.dumpleader.com/DP-750_exam.html


                                                      Related Links: myportal.utt.edu.tt myportal.utt.edu.tt myportal.utt.edu.tt myportal.utt.edu.tt myportal.utt.edu.tt myportal.utt.edu.tt

                                                      Leave a Reply

                                                      Your email address will not be published. Required fields are marked *

                                                      Enter the text from the image below